ProjectsFlagship
NYC Taxi dbt Analytics
Dimensional models with dbt and DuckDB: 109,047,518 yellow trips at source, 8,298,395 sampled facts, and 34 tests executed in CI.
Overview
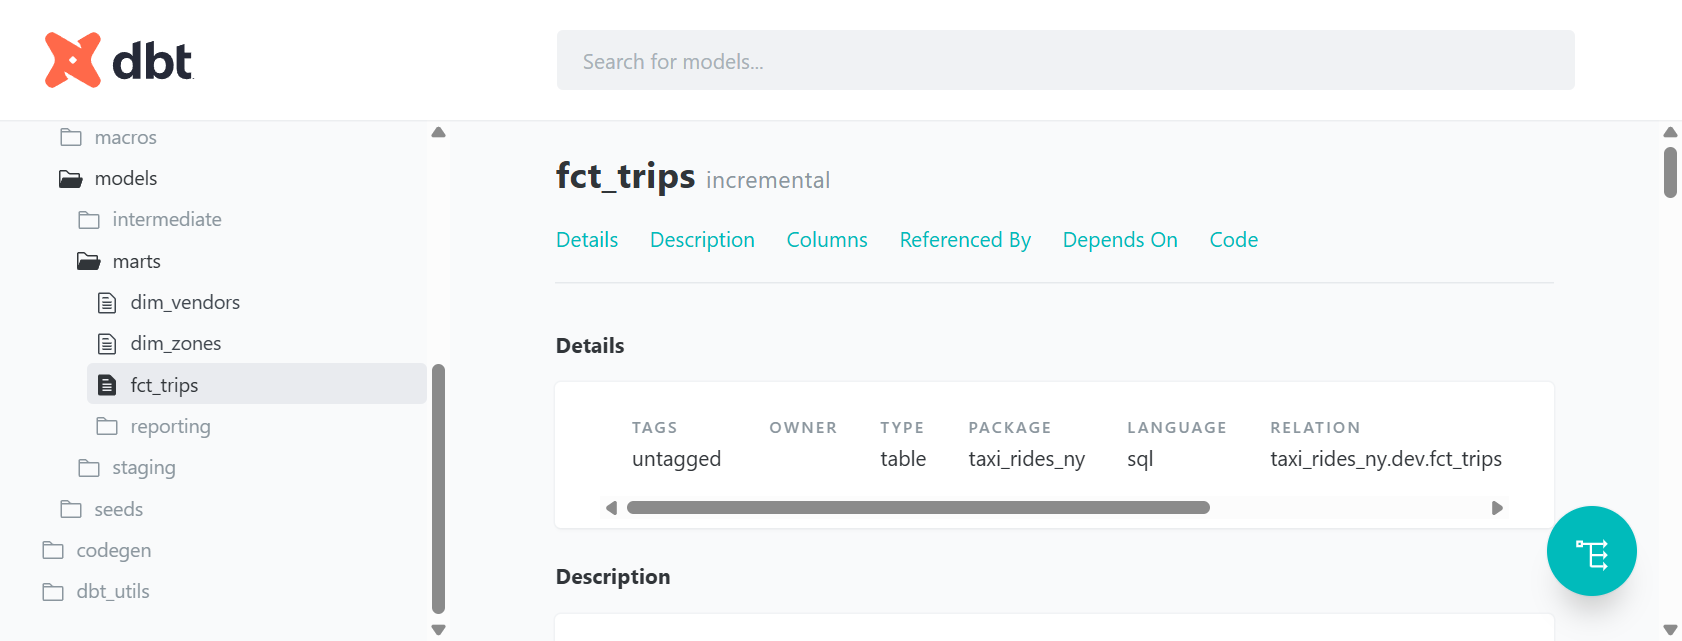
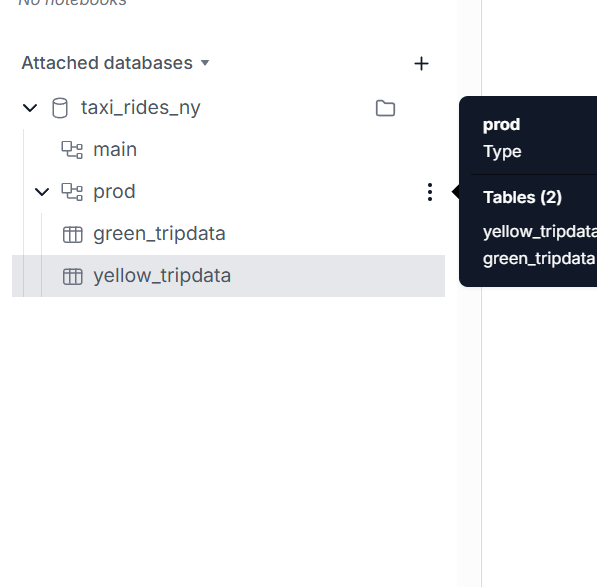
An analytics-engineering warehouse for NYC yellow and green taxi trips. ingest_data.py lands monthly files as Parquet in DuckDB (prod schema). dbt then builds staging, intermediate, and marts — dimensions for zones and vendors, an incremental fct_trips, and monthly zone revenue. Seeds, macros, dbt_utils, and generated docs are in the repo. Coursework from DataTalksClub Zoomcamp module 04, run locally instead of BigQuery.
Interface
Problem
TLC publishes tens of millions of trip rows with inconsistent yellow/green column names. Analysts need typed, documented models and a grain they can join — not a pile of CSVs.
Technical solution
Load Parquet into DuckDB, then build staging → intermediate → marts with dbt. The intermediate layer now derives trip_id from the complete stable trip grain; a weaker shortcut was found to collapse 202,906 valid rows. The corrected model retains all 8,298,395 January records, and a deterministic CI fixture prevents regression.
What is in the repository
- ingest_data.py: CSV.gz → Parquet → DuckDB prod schema
- Staging for yellow and green with shared naming
- Star schema: dim_zones, dim_vendors, incremental fct_trips, fct_monthly_zone_revenue
- Seeds for taxi zones and payment types; macros including safe_cast and trip duration
- dbt packages: dbt_utils, codegen; dbt docs generated and served locally
Technical decisions
- DuckDB instead of BigQuery for the local warehouse
- The Zoomcamp module targets BigQuery. This repo keeps the same modeling ideas on a laptop-sized DuckDB file so the work is reproducible without a cloud bill.
- Incremental facts
- fct_trips merges on trip_id so later months can append without rebuilding 8M+ rows from scratch.